
I've been following a tufte-jekyll styled blog for a couple of years and that led me to discover Edward Tufte's book layout.
Edward Tufte is renowned for his work on data visualization and information design, and he's a fierce advocate of high data density and for the removal of "chartjunk".
This is what tufte-css (and its many ports, including this one) brings to the web: generous whitespace, a serif reading column, and precious sidenotes for supplementary information (instead of disruptive modals).
I liked almost everything about tufe-jekyll blogs except the parts that had nothing to do with writing: a Jekyll powered Ruby version I only ever touched for this one project.
So I rewrote the whole theme in Python. Not because Jekyll is bad. It isn't. But because I wanted a toolchain I'm comfortable with. I was also curious whether I actually understood and could assimilate how a static site generator works.
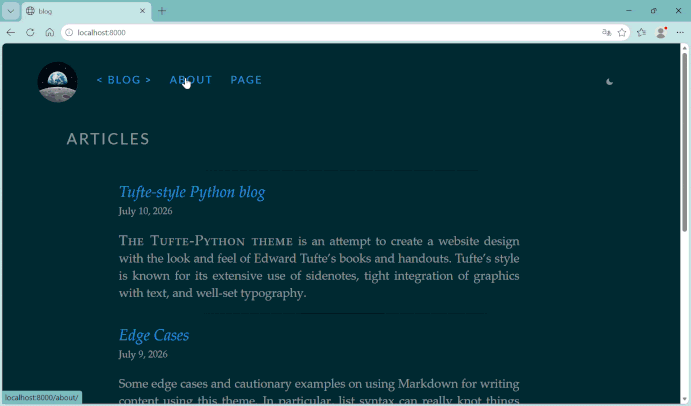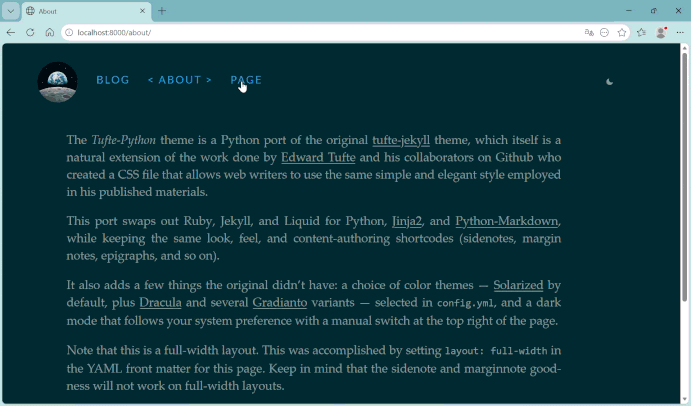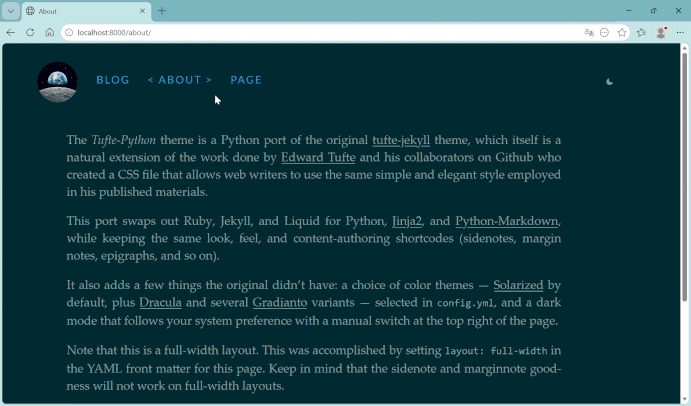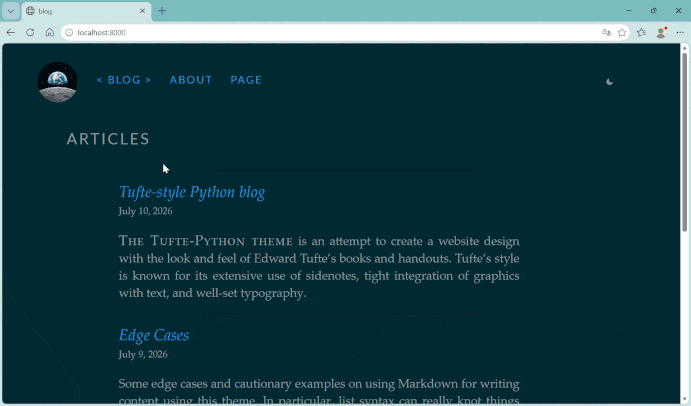
tufte-python is that port and this write-up acts as a guide: what actually has to happen when you move a Liquid-based Jekyll theme to a Python one, and the specific places I got it wrong before I got it right.
None of this is Jekyll-specific advice. The same pattern applies whether your target is Hugo (GoLang), Eleventy (JavaScript), or something else.
Here, you'll tinker on very focused technical points but also discover a way to break things down. If you're porting a different theme, or porting to a different language entirely, remember: the syntax changes but the shape of the challenge is the same.
Table of Contents
Step 5: Swap Filesystem-Watching for an Explicit Build Cache
Step 6: Replace Jekyll's Native GitHub Pages Build With Your Own CI
But Wait, Why a Static Blog?
Compared to dynamic websites, a static site has a simple publishing workflow. In this case, it consists of five steps:
Write a Markdown file.
Run the generator.
Preview and review the result.
Commit the source files.
Let GitHub Actions publish the site.
This workflow is simple enough for the needs I have: occasionally publishing posts on my personal Dev blog. It keeps the content readable in a text editor and makes every change easy to review.
Like its predecessor, the actual codebase keeps Jinja2 templates, Markdown, and a YAML front matter for contents. A GitHub Actions workflow builds the site and deploys the generated _site/ directory to GitHub Pages.
Why Port a Theme Instead of Just Using It As-Is ?
There are various reasons for doing it this way.
First, maybe you want out of a toolchain you don't use anywhere else. For me that was Ruby installed on my machine for exactly and only this purpose. It was flaky enough that update my blog occasionally turned into fix my Ruby environment first.
Or maybe you already write in the target language daily, and would rather read and extend a generator you're fluent in than learn just enough of another ecosystem to (eventually) tweak a plugin file.
Or perhaps you want to understand static site generators, not just operate one. Porting forces you to read every template, every custom tag, and every build step closely enough to re-implement it. You learn and retain information differently. It's a very different level of understanding than oh! it works, and it's one of the best ways to achieve mastery.
What You'll Need
Basic Python: virtual environments, reading someone else's code.
Git and a GitHub account, since the destination for both versions is GitHub Pages.
Familiarity with Markdown and Git (you can even learn it as a game).
Basic familiarity with Jekyll's project layout:
_config.yml,_layouts/,_includes/, and Liquid template syntax.No prior Jinja2 experience required. It's close enough to Liquid conceptually that you'll pick it up as you go.
See the Destination First: Get the Finished Port Running
Before I get into how the port actually came together (including the parts that broke), it's worth seeing where it ends up. The theme I'm describing already exists as a ready-to-ship project. tufte-python comes with its own tutorials and you can have it running locally within minutes.
This gives you something concrete to compare against as you read the rest of this, and something to fork if you'd rather adapt an existing port than build your own from zero.
Setup
First, clone it and point it at your own repository (or fork it)
Start by creating a new, empty repository on GitHub. Give it a name such as my-blog:
git clone https://github.com/hyperphantasia/tufte-python.git my-blog
cd my-blog
Next, change the origin remote to point to your repository
git remote set-url origin <your-repository-url>
Then push the project:
git push -u origin main
Next, install the dependencies in a virtual environment
python -m venv .venv
# Uncomment to match your OS
# source .venv/bin/activate      # macOS/Linux
# .venv\Scripts\Activate.ps1     # Windows PowerShell
pip install -r requirements.txt
Now you'll want to set basic configuration values before your first build.
Open config.yml at the project root:
title: "A Quiet Corner of the Web"
author: "Your Name"
email: "you@example.com"

url: "https://yourusername.github.io"
baseurl: "/my-blog"              # "" instead, if this is a user/org page
permalink: "/articles/{year}/{slug}/"

theme: "solAArized"
options:
  mathjax: true
If you're publishing at https://yourusername.github.io/my-blog/, baseurl needs to match the repository name exactly, leading slash and no trailing slash. If you get this one wrong, every internal link and stylesheet reference on the deployed site will 404 while working fine locally (more on why in the point below).
Finally, build and preview it:
python build.py --serve --watch
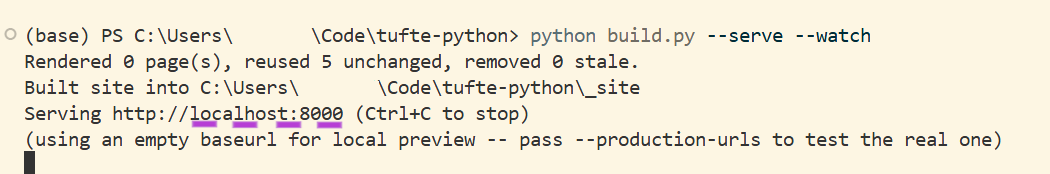
Open the address the terminal prints http://localhost:8000 (usually) and you should see the demo content that is already in content/. Leave --watch running and edit a post: the page rebuilds without you re-running anything.
One thing is worth knowing now before it costs you a confusing afternoon later: the local --serve preview ignores baseurl on purpose, so links and assets resolve from the root of your dev server instead of a subdirectory.
If you want to check the site exactly as it'll look once deployed, including the real baseurl: run python build.py --serve --production-urls instead. This is meant to preview the site using the production URL structure.
That distinction is the entire reason the works locally, breaks in production bug exists for static sites in subdirectories, and it's worth deliberately testing both modes at least once before you deploy for real.
Write your First Post
You can see the theme's features render on your own content instead of the demo's. Create content/posts/2024-06-07-hello.md:
---
title: "Hello, Margins"
date: 2024-06-07 14:30:00
categories: notes
tags: [smile, writing]
---

{% newthought 'A new thought' %} can open a section without another heading.

Here's a sidenote{% sidenote 'note-1' 'This appears in the right margin on wide screens, and behind a tap target on narrow ones.' %} to try the feature that made me want this theme in the first place.

<!--more-->

Everything past the `<!--more-->` marker stays off the homepage excerpt but shows up on the full post.
Many other visual features are available. They are discussed in details below, during implementation.
Rebuild (or let --watch pick it up), and you should see a small-caps opening phrase and a numbered note sitting in the margin next to the paragraph that references it. If both of those render, the theme's core mechanism is working end to end on your machine, good! This is the mechanic the rest of this tutorial is all about.
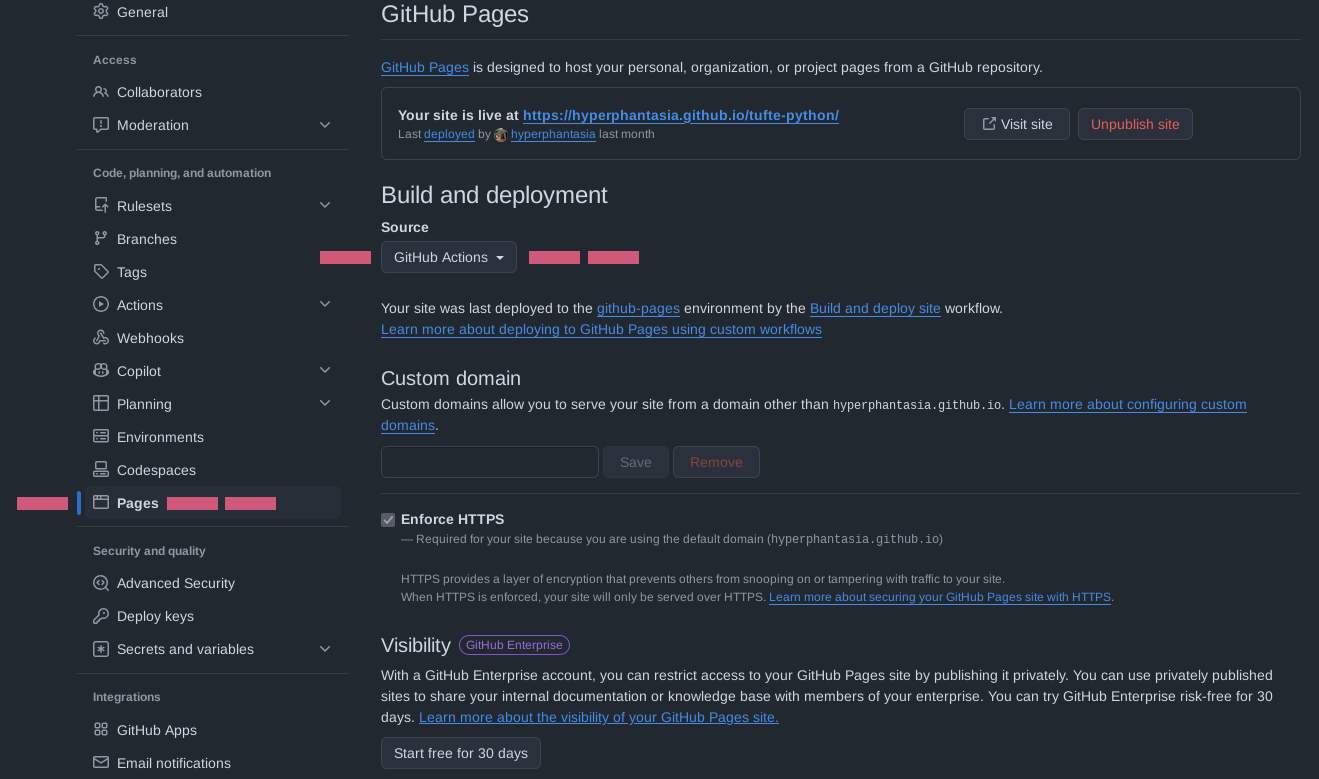
In your repository's Settings → Pages, set the source to GitHub Actions if it isn't already. The workflow bundled with the project builds and deploys automatically on every push to main. I'll walk through what that workflow is actually doing in Step 6, since GitHub Pages doesn't know what to do with a Python build script.
Ship it once you're happy with it locally:
git add config.yml content/
git commit -m "Configure site and add first post"
git push
With that running, you've got a working reference point online. Now here's how it got built.
From tufte-jekyll to tufte-python, Step by Step
To migrate a Jekyll theme to a Python build system, it's important to follow structural steps that deconstruct the existing setup.
Here, I determined six high-level steps, but that can vary depending on your task. It's very important to "own" the result in your mind first. This approach will enable you to consolidate a configuration and modernize the tooling with minimal breaks during the process.
Step 1: Inventory the Source Theme's Moving Parts
Before writing any Python, I listed every piece of Jekyll machinery the theme actually depended on. For this Liquid-heavy theme, that breaks into four categories:
| Jekyll piece | What it does | Expected Python equivalent |
|---|---|---|
_config.yml + _data/*.yml |
Site metadata, base URL, permalink pattern, feature toggles, structured data like social links | One config.yml |
_layouts/ + _includes/ |
Page templates and partials | A templates/ directory of Jinja2 templates |
_plugins/*.rb |
Ruby classes registering the theme's custom Liquid tags | A small Python module expanding the same tag syntax |
_sass/*.scss |
Sass partials compiled into one stylesheet at build time | Plain CSS files, no compile step |
I missed a fifth category on my first pass: the original theme ships two separate Rake tasks, one for scaffolding new posts and pages, and a completely different one: UploadToGithub.Rakefile for pushing the built site to a gh-pages branch by hand.
This is needed because the theme's plugins aren't in Jekyll's Pages-safe allowlist. I'd read the main Rakefile and assumed I had the whole deploy story, then wondered for some time how the original author actually got the site live.
Advice: read the whole repository root, not just the files with obvious names, before you commit to a structure.
Step 2: Collapse Scattered Config Into One File
The Jekyll version spreads settings across _config.yml (site title, URL, baseurl, permalink pattern) and one or more files under _data/: a toggle for MathJax and font loading in one file, a list of social links in another. That split follows Jekyll's own data-file conventions, but it's a complexity you don't need when you're writing your own (minimal) loader.
I consolidated all of it into a single file with clearly named sections, so anyone extending the theme later can find every setting in one place instead of three. You get something like this:
# config.yml
# --- site metadata ---
title: "A Quiet Corner of the Web"
author: "Your Name"
email: "you@example.com"

# --- URL settings ---
url: "https://yourusername.github.io"
baseurl: "/my-blog"
permalink: "/articles/{year}/{slug}/"

# --- feature toggles (previously in _data/options.yml) ---
mathjax: true
justify_text: false

# --- social links (previously in _data/social.yml) ---
social:
  - link: "github.com/yourusername"
    icon: icon-github
Step 3: Rebuild Custom Liquid Tags as Text Shortcodes
This is the part that took the longest to tinker with. It's also where most of the theme's actual personality lives. This is where you actually build the visual features: sidenotes, margin figures, and epigraphs.
How Jekyll does it
Custom Liquid tags live in _plugins/, as Ruby classes Jekyll registers with its Liquid parser. Jekyll expands them during its Liquid render pass, before handing the result to its Markdown engine.
A tag like {% sidenote "note-1" "Some aside." %} never reaches the Markdown converter as-is. It's already been swapped for HTML by the time Markdown sees the page.
Why you can't just port this 1:1 into Jinja2.
Jinja2 has its own tag system, but it's built for template-authoring logic (with loops, conditionals, and so on) not for parsing arbitrary quoted arguments out of prose sitting inside a Markdown file. And even if I'd built a Jinja2 extension for it, every existing post using the old {% sidenote ... %} syntax would need rewriting. This catch defeats the entire point of a drop-in port.
What Actually Works
Treat the tag syntax as plain text, and expand it with a preprocessing pass over the raw Markdown, before handing it to the Markdown renderer. The strategy is to mirror Jekyll's own tag-then-Markdown order exactly. A simplified version of that pass looks like this:
import re, shlex

TAG_RE = re.compile(r"\{%\s*(\w+)\s*(.*?)\s*%\}")

def split_args(raw: str) -> list[str]:
    lexer = shlex.shlex(raw, posix=True)
    lexer.whitespace_split = True
    return list(lexer)

def render_sidenote(args, resolve_img, render_md):
    note_id, text = args[0], args[1]
    text = render_md(text)
    return (f"<label for='{note_id}' class='margin-toggle sidenote-number'>"
            f"</label><input type='checkbox' id='{note_id}' "
            f"class='margin-toggle'/><span class='sidenote'>{text}</span>")

HANDLERS = {"sidenote": render_sidenote}  # All visual features are registered here

def expand_shortcodes(text: str, resolve_img, render_md) -> str:
    def dispatch(match: re.Match) -> str:
        name, raw_args = match.group(1), match.group(2)
        handler = HANDLERS.get(name)
        if handler is None:
            return match.group(0)  # leave unknown tags untouched
        return handler(split_args(raw_args), resolve_img, render_md)
    return TAG_RE.sub(dispatch, text)
The snippet above acts as a custom "search-and-replace" engine that converts shorthand tags into HTML before the final page is rendered. It uses a regular expression to scan the text for patterns like {% tag arguments %}.
The Regex (TAG_RE) is the "Scanner":
The regex is responsible for finding the tags in the big block of text. It breaks every match into two specific groups:
Group 1 (the name): the word immediately after {% (for example, "sidenote").
Group 2 (the raw arguments): everything else until the closing %} (for example, "note-1" "Some aside.").
expand_shortcodes is the "Coordinator":
This function manages the overall process. It uses re.sub to loop through the text. Every time the regex finds a match, expand_shortcodes triggers the dispatch function, which does two things:
It uses the name from Group 1 to look up the correct logic in the
HANDLERSdictionary.It passes the raw arguments from Group 2 into
split_argsbefore sending them to the parser.
split_args is the "Parser":
split_args uses the shlex library to "smart-split" the string. It recognizes quotes, so that anything inside quotation marks is kept together as a single argument. This produces a clean list where Arguments containing spaces, like a sentence inside quotes are treated as a single piece of data rather than multiple separate words (for example, ['note-1', 'Some aside.']). The final handler function can easily process that.
Render:
The last step is the actual rendering. Each tag name identified in the HANDLERS dictionary is tied to a specific Python function that knows how to return the corresponding HTML markup (for example, render_sidenote() for sidenotes).
You can have a look at the .sidenote and .margin-toggle CSS classes, to grasp an idea of how they behave visually.
Two bugs taught me why the details above matter. Both were found by throwing real old posts at the new build instead of just the demo content:
Quoting broke first. My first argument splitter was
raw.split()on whitespace. It worked fine until I fed it a post with an apostrophe in a sidenote.Example: "reader's" is problematic. It split into two arguments and shift every argument after it by one. Liquid's own tag documentation actually spells out the fix: accept either single or double quotes, and allow a backslash to escape a quote inside the text.
shlexin POSIX mode does exactly that in about two lines, which is a smaller fix than the bug deserved.Code fences broke second. I wrote a post explaining the shortcode syntax itself, with an example wrapped in a fenced code block. This is a case of context-blindness. The regular expression is designed to find the pattern
{% ... %}anywhere it appears in the document, but it doesn't know the difference between "live" code that should be executed and "example" code that is just meant to be displayed as-is to the reader.The expand_shortcodesfunction sees the{% and %}inside that code block and says, "Aha! A visual feature!" It then replaces the example text with the actual HTML for a sidenote and you end up seeing a broken layout where a functional feature is floating inside a code block.The fix is to stash fenced and inline code spans behind placeholders (like
##CODEBLOCK_1##) before running the tag regex, then restore them afterward.
The Rendered Features
The margin is not decoration. The Tufte-inspired layout remains readable thanks to the restrained typography and a generous margin set for supporting materials.
Secondary information moves into the margin instead of becoming a long interruption in the body of the article. It gives other visual elements such as notes, references, and figures a unique place to live without interrupting the main argument.
From there, porting the rest of the tags was repetitive and mechanical: same pattern, a different handler and argument count each time, the entire code is available in this file and this is how they render:
New Thought:
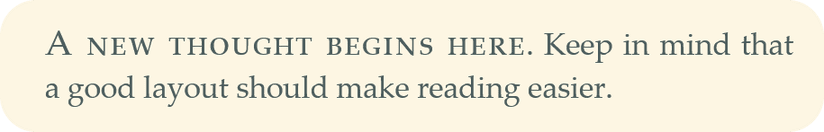
- Liquid tag:
{% newthought 'text' %}
Sidenote:
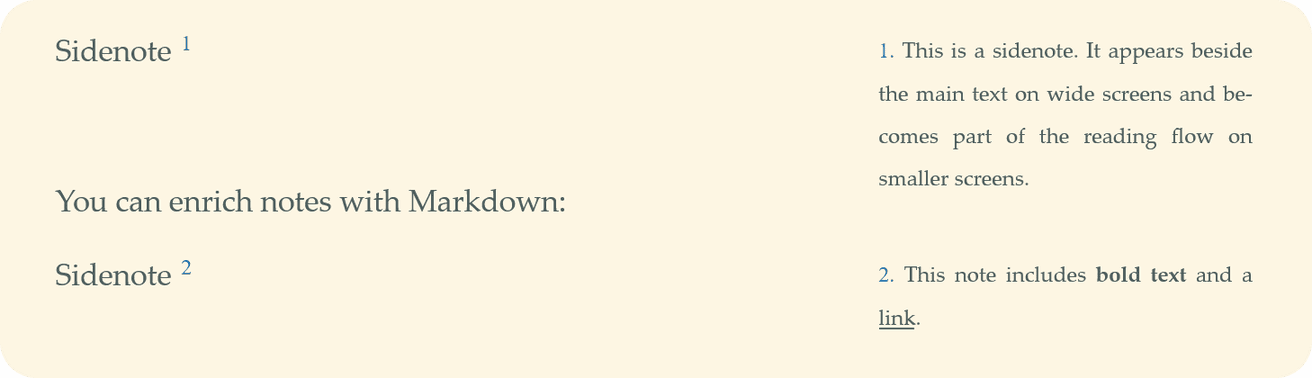
Liquid tag:
{% sidenote 'id' 'text' %}Sidenotes are numbered aside in the right margin.
Margin note:
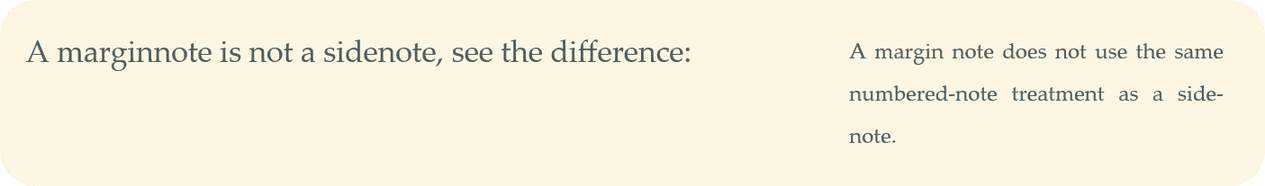
Liquid tag:
{% marginnote 'id' 'text' %}Margin notes are unnumbered aside in the margin.
Margin figure:
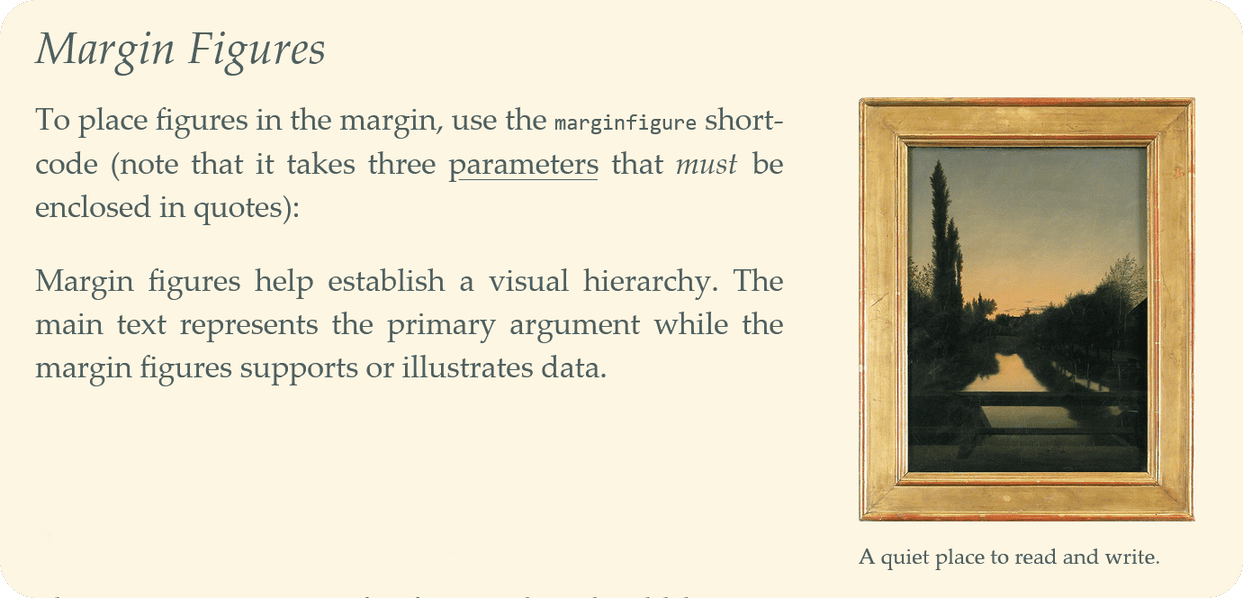
Liquid tag:
{% marginfigure 'id' 'path' 'caption' %}The supporting image is confined to the margin column. Handling images isn't a big challenge, since HTML provides
imgtags. Positioning them correctly within the viewport is bit more tricky but was already handled well by the original SCSS.
Main column figure:
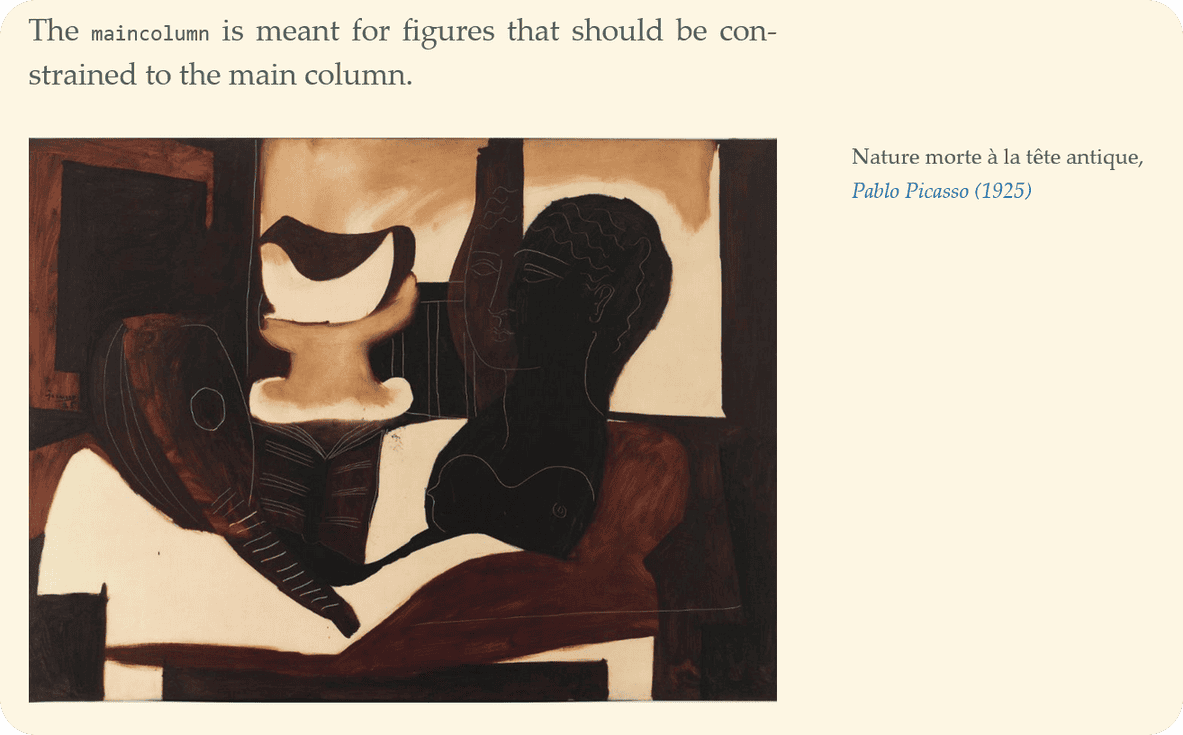
Liquid tag:
{% maincolumn 'path' 'caption' %}The main image is confined to the main text column.
Full-width figure:
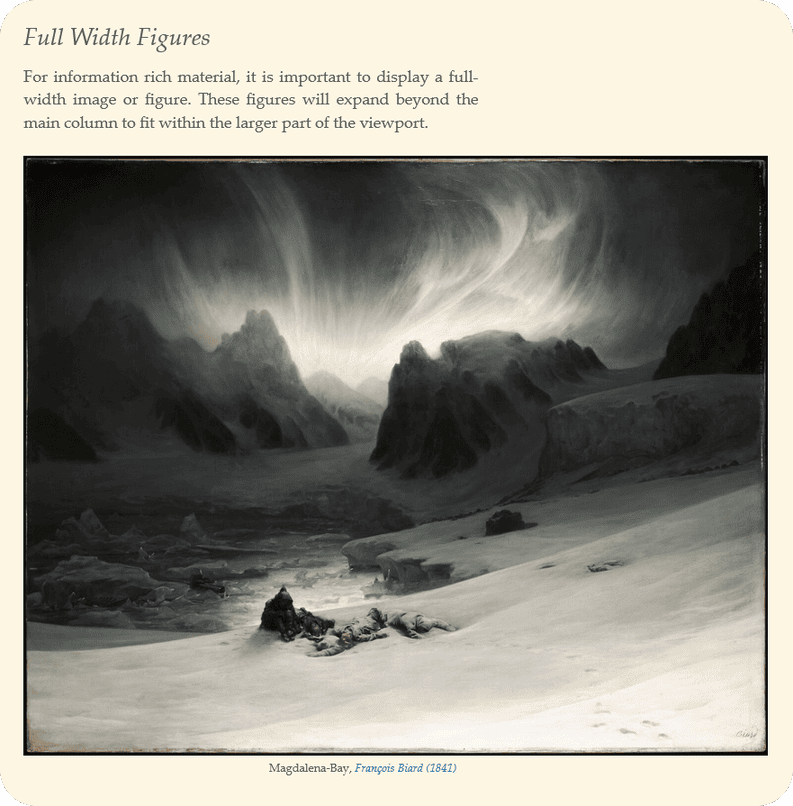
Liquid tag:
{% fullwidth 'path' 'caption' %}The full image spans on both columns.
Epigraph:
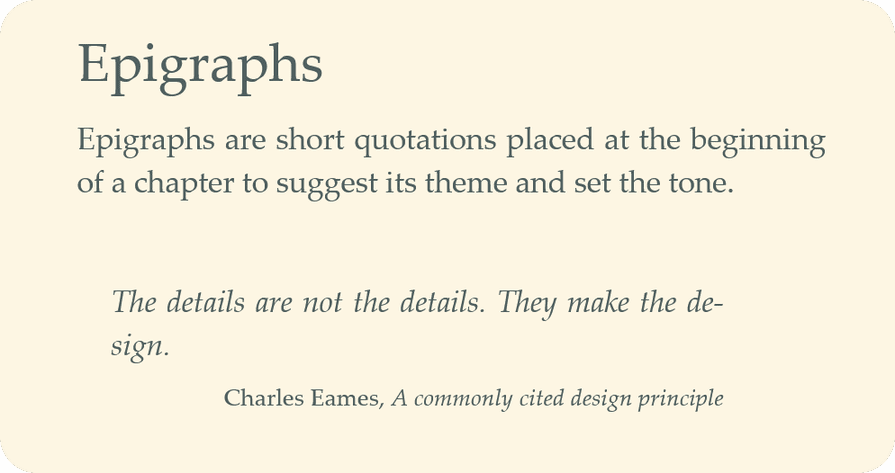
Liquid tag:
{% epigraph 'quote' 'author' 'source' %}This is meant for a standalone attributed quotation.
Math:
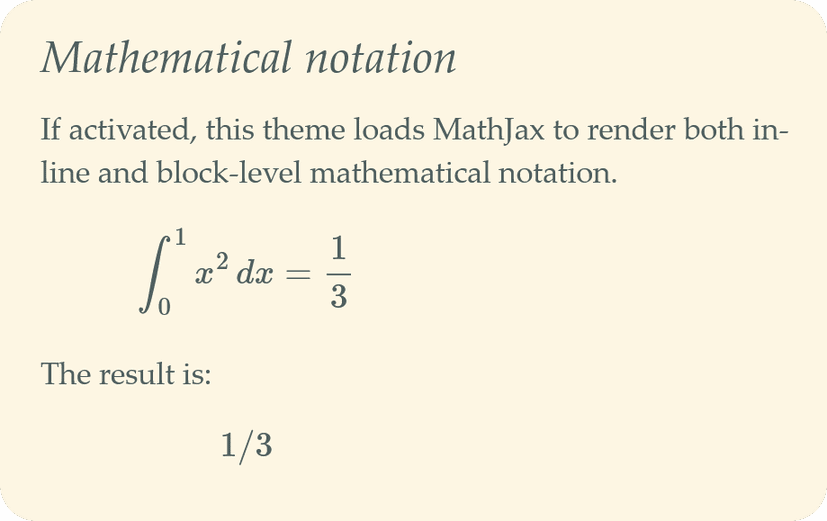
You can also use standard markdown features, like code snippets:
or tables:
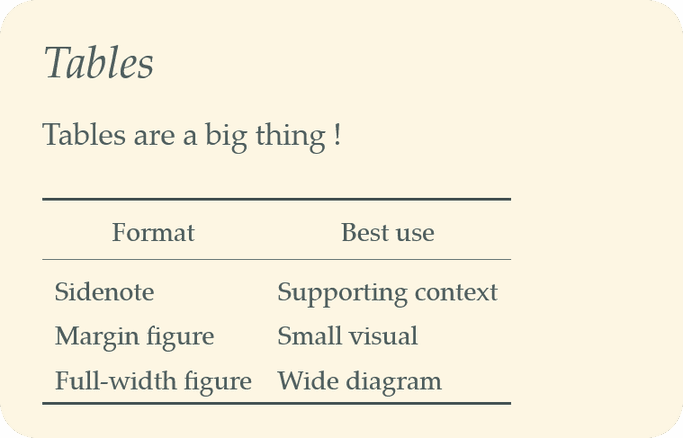
These last two elements were easier to implement. Since they render in pure Markdown, it really is just about handling them directly in the CSS style sheet (for example, the Table styling section in the tufte.css file).
Step 4: Replace Compiled Sass With Swappable Plain CSS
Jekyll's Sass pipeline compiles _sass/ partials into a single stylesheet at build time, baking one fixed color palette into the output.
I didn't want a Sass-compilation dependency just to port a theme, so I stopped compiling colors into CSS.
The plain CSS stylesheet comes into two layers: structural CSS that never hardcodes a color, only references custom properties like color: var(--color-text), and one small theme file per palette that defines nothing but --color-* properties. The build copies just the selected theme's file into the output, based on a theme: key in config.yml.
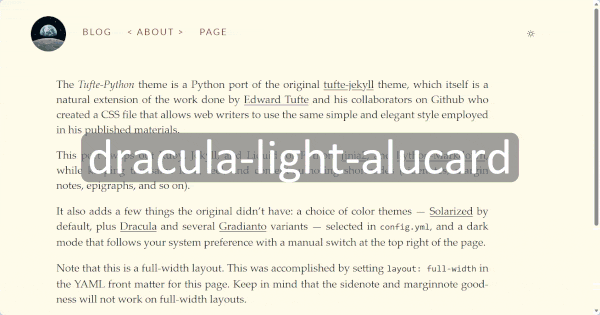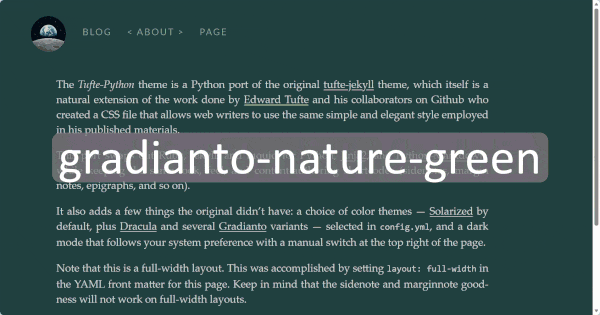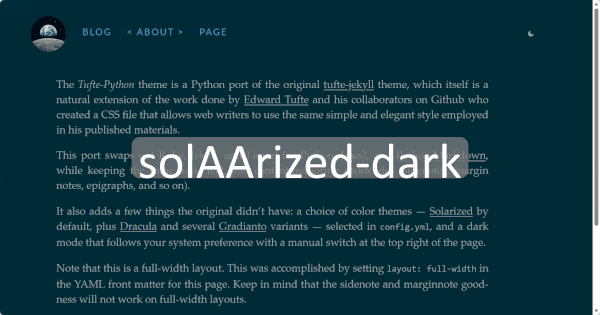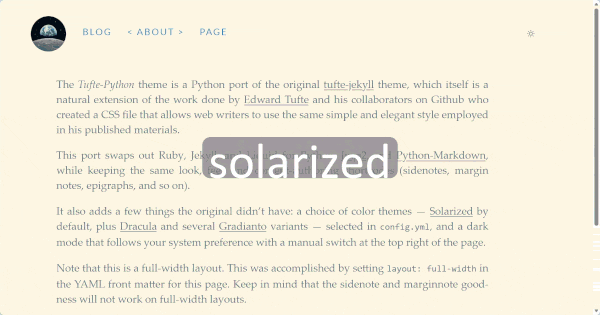
Custom themes were a big improvement I wanted to implement. This turned into more than a workaround once I actually checked the numbers. I'd defaulted to Solarized first because I liked it, and only later discovered it's not optimal in terms of accessibility. That's a known, documented property: it trades some contrast for reduced eye strain.
Shipping it as the default without flagging it felt wrong for something other people might actually use to read.
Since the theme system is just swappable CSS files, the fix was adding one more file: a WCAG 2.0 AA accessible variant with the same palette adjusted to clear 4.5:1 contrast, alongside the original. That's the option this tutorial's config example points at: solAArized.
The custom-properties approach paid off again a moment later: because colors are resolved at runtime by the browser instead of baked in at build time, adding a light/dark toggle driven by prefers-color-scheme was just a small JS file to wrap. This is something a Sass-compiled single palette can't do without recompiling twice.
Step 5: Swap Filesystem-Watching for an Explicit Build Cache
jekyll serve -w bundles file-watching and incremental regeneration. Incremental involves tracking the actual state.
My first cache just tracked each post's own modification time: unchanged file, skip re-rendering. That's correct right up until you edit a shared template. I changed the post layout, rebuilt, and only two of my posts picked up the change: the ones I'd also touched that day. The others were "unchanged" by the only definition the cache knew about, so they kept their stale, pre-edit HTML in _site/.
The fix is a second, separate timestamp that isn't tied to any one document: track the newest modification time across global build inputs: templates, config.yml, and the generator's own source. If any of those is newer than the cache, force a full rebuild regardless of what any individual post's timestamp says.
import json
from pathlib import Path

CACHE_FILE = Path(".build_cache.json")

def load_cache() -> dict:
    if not CACHE_FILE.exists():
        return {"global_mtime": 0.0, "docs": {}}
    return json.loads(CACHE_FILE.read_text())

def needs_rebuild(src: Path, out: Path, cache: dict, global_stale: bool) -> bool:
    if global_stale or not out.exists():
        return True
    cached_mtime = cache["docs"].get(str(src))
    return cached_mtime is None or src.stat().st_mtime > cached_mtime

def save_cache(cache: dict, docs: dict) -> None:
    cache["docs"] = docs
    CACHE_FILE.write_text(json.dumps(cache))
The load_cache() function reads a saved JSON file that remembers when each document was last modified or it creates a fresh empty cache if the file doesn't exist yet.
The needs_rebuild() function checks whether a source file actually needs to be rebuilt by comparing its current modification time with the timestamp stored in the cache. If the file is newer than what's cached, or if the output file doesn't exist, it returns True (meaning "rebuild needed").
Finally, save_cache() updates the cache with the new build information and saves it back to the JSON file, so next time you run your build, you can skip files that haven't changed.
There's no cheap way to know which pages a shared template actually touches without re-parsing everything, so I stopped trying to be clever about it. It costs one slower build after a template edit but that's in exchange for never silently shipping a page that looks like it built successfully but didn't actually pick up the change.
Step 6: Replace Jekyll's Native GitHub Pages Build With Your Own CI
GitHub Pages knows how to build Jekyll natively. It has no idea what python build.py means, so the port needs its own CI step to build the site and hand the output to Pages:
# .github/workflows/deploy.yml
name: Build and deploy site
on:
  push:
    branches: [main]

jobs:
  build:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-python@v5
        with:
          python-version: "3.12"
      - run: pip install -r requirements.txt
      - run: python build.py
      - uses: actions/upload-pages-artifact@v3
        with:
          path: _site

  deploy:
    needs: build
    runs-on: ubuntu-latest
    permissions:
      pages: write
      id-token: write
    steps:
      - uses: actions/deploy-pages@v4
What happens? When you push, GitHub's servers automatically run the build job, which checks out your code, installs Python 3.12, downloads the project dependencies (from requirements.txt), runs build.py to generate the website, and then uploads the generated _site folder as an artifact.
After that succeeds, the deploy job automatically runs and takes that artifact to publish it live to GitHub Pages. Note the needs: build line. It validates the deploy step only happens after the build completes successfully, so you can't accidentally deploy a broken build.
This is the workflow the quickstart earlier in this piece relies on. Remember that in Settings → Pages, the source has to be set to GitHub Actions rather than a branch (this replaces Jekyll's built-in build step entirely). I missed that setting the first time and spent a few minutes convinced the workflow had silently failed, when it had actually succeeded and just had nowhere configured to deploy to.
Step 7: Verify Feature Parity, Not Just "It Builds"
A port that compiles cleanly isn't necessarily a correct one. Every bug I've described above passed a clean build first. Before I called it done, I tested against:
Real, unmodified posts from the original theme, not just demo content. This is what actually caught the quoting bug and the code-fence bug, neither of which showed up until I stopped testing against content I'd written specifically to be easy.
Quoting edge cases deliberately: an apostrophe inside a note, Markdown formatting inside a note, an escaped double quote.
Responsive behavior, since sidenotes and margin notes that tap-to-reveal on narrow screens are easy to get right on desktop and silently break on mobile versions.
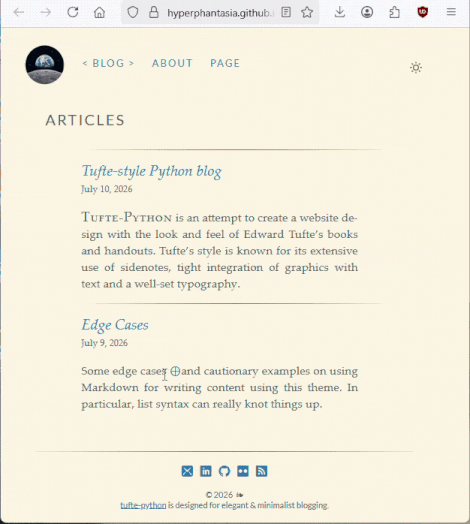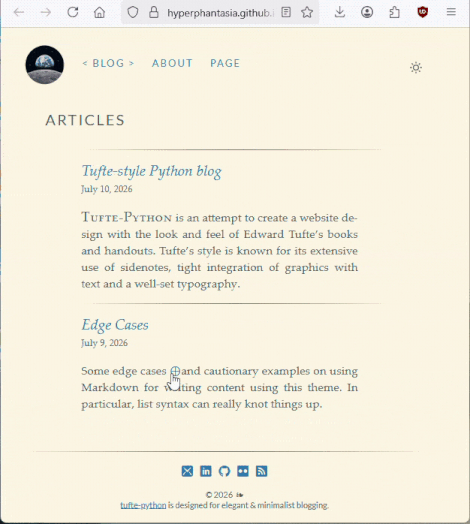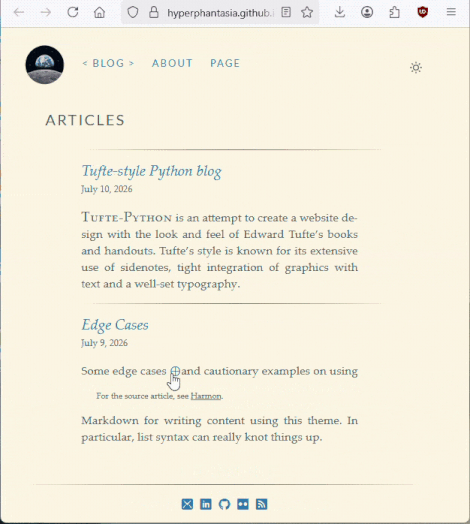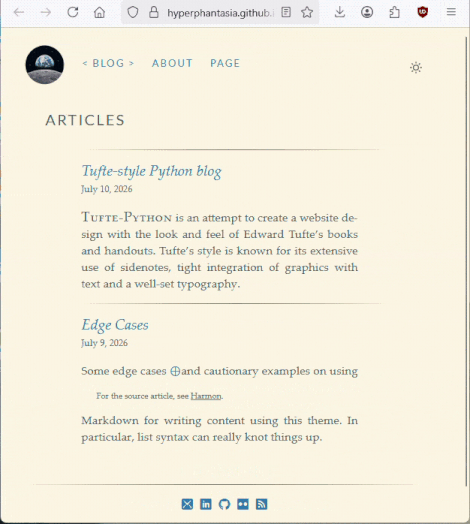
Responsive design is sometimes neglected and definitely not an option regarding nowadays devices diversity. Always consider it as a full and distinct user experience.
What I'd Tell Myself at the Start
Every real bug in this port came from the same root cause: testing against content I'd written to be easy, instead of content that already existed.
Don't have opinions about how the old tags should behave. The fix, every time, was the same instinct: go find the actual edge case in the old repository's documentation and code, rather than guessing at what "probably" needs to be supported.
The steps themselves generalize past this one theme: inventory the source generator's moving parts, consolidate its config, re-implement custom tags as a text-preprocessing pass instead of fighting your new template engine's syntax, swap compiled styling for something your new stack can produce without extra tooling, write your own incremental cache with an explicit escape hatch for global changes, replace whatever native deploy step you're leaving behind with your own CI, and verify against real content, not a clean build. That holds whether you're moving from Jekyll to Python, Python to Go, or anywhere else.
Thanks for reading! Feel free to contribute to tufte-python! I'm very curious about what you can come with to make this library better. More personal projects are available on my GitHub and Kaggle. You can also connect with me directly on LinkedIn as well.